Blog AI in Security
What Happens When Your Security Tools Know Too Much?
LLMs are moving into the core of security operations. Unlike search engines, they aggregate and synthesise what they learn about your environment — on infrastructure you do not control. Seven governance rules for using them anyway.
Introduction
Security has never been a single-layer problem. From the moment we start designing a product or an infrastructure environment, we enter a continuous cycle spanning architecture, implementation, deployment, testing, monitoring, and incident response. Each phase demands access to external knowledge — threat intelligence feeds, vulnerability databases, CVE repositories, vendor advisories, penetration testing frameworks, and more.
For years, this knowledge has been distributed. It lived across dozens of platforms: a search engine here, a SIEM knowledge base there, a threat intel portal somewhere else. That distribution was inconvenient, but it also meant that no single external system ever held a complete picture of your vulnerabilities, your architecture, and your response capabilities simultaneously.
Large Language Models are changing that equation — and the security community needs to examine the implications seriously before the cost of not doing so becomes visible.
Part IThe security lifecycle and its external knowledge dependency
To understand the risk, we must first appreciate how deeply external knowledge is woven into security work at every phase.
Design and architecture. Before a line of code is written, security architects consult threat modeling frameworks, reference architectures, known attack patterns, and compliance requirements. They query search engines, read whitepapers, and consult vendor documentation to understand how to build systems that are resilient by design.
Implementation. Developers look up secure coding patterns, search for known vulnerabilities in libraries and dependencies, and reference security standards. Every “how do I implement this securely?” query externalizes a small piece of what is being built.
Deployment and configuration. Infrastructure teams search for hardening guides, benchmark configurations, and known misconfigurations for the platforms they are deploying. Search queries implicitly reveal the technology stack in use.
Penetration testing and vulnerability assessment. Security testers query exploit databases, look up CVE details, research attack techniques through frameworks like MITRE ATT&CK, and search for proof-of-concept code. Every query reflects what is being tested — and therefore what exists in the environment.
Security monitoring. SOC teams build detection use cases by researching attacker behaviors, querying threat intelligence platforms, and looking up indicators of compromise. The detections they build reveal what threats they are concerned about and, implicitly, what they may not yet be detecting.
Incident response. During an active incident, analysts query threat intelligence platforms, malware repositories, and forensic databases. They search for the exact artifacts they have found in their environment — hashes, domains, behaviors — which directly reveals what they are dealing with and where they stand in their response.
The common thread: knowledge flows outward to enable security work. This has always been true. What has changed is the nature of the systems receiving that knowledge.
Part IIHow search engines understood us — and what they did not
For decades, Google and similar search engines were the primary tool for externalizing security queries. It is worth being precise about the risk profile, because we have largely normalized it without fully thinking through the implications.
When a security analyst searches for “Apache Log4j exploitation detection methods,” they reveal an interest in a specific vulnerability class. When an architect searches for “zero trust network segmentation AWS VPC,” they reveal something about their cloud environment.
However, a search engine receives only a short, decontextualized query. It has no idea what your network looks like. It does not know whether you have patched Log4j. It does not know that the VPC query came from the same organization that searched for “IAM privilege escalation detection” last week. Each query is a thin sliver of signal, largely disconnected from all others.
Search engines also return pointers, not conclusions. A human analyst must read results, apply judgment, and reach their own conclusions. The cognitive work of understanding your specific security posture happens entirely inside your walls, performed by your people using their knowledge of your environment.
The risk is real — but characterized by its thinness and distribution. No single interaction reveals very much.
Part IIIHow LLMs understand us — and why it is fundamentally different
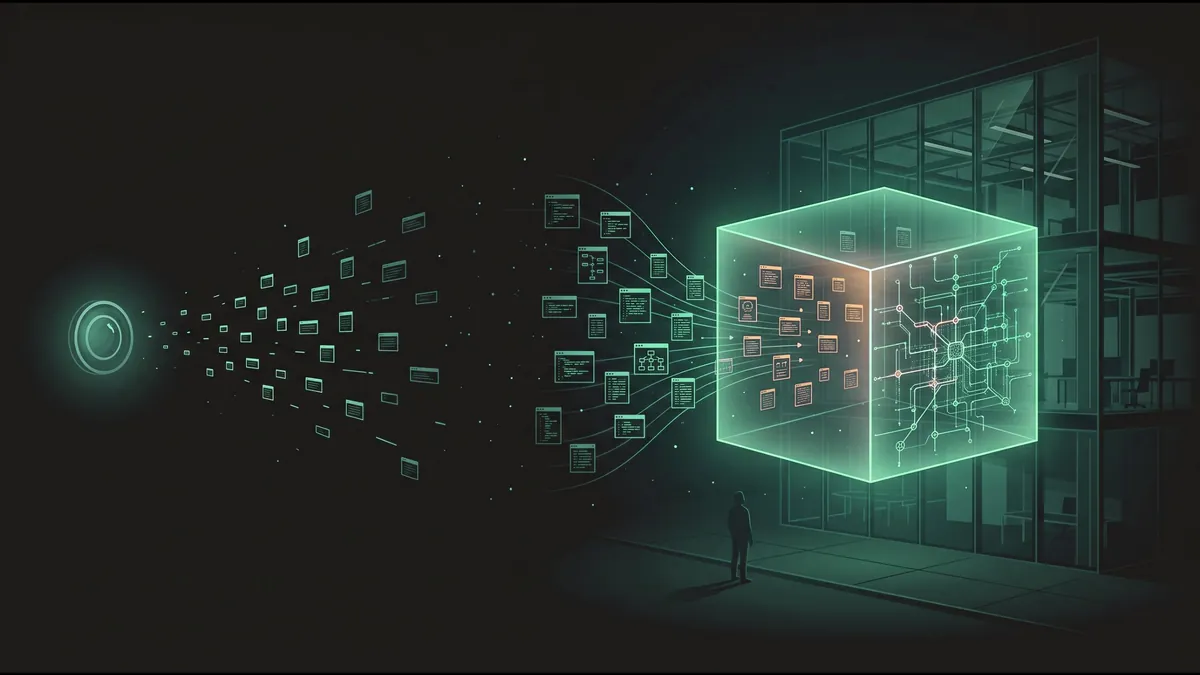
Large Language Models operate on an opposite principle. Their value proposition is: instead of returning pointers to existing content, they reason over rich, specific context that you provide to produce synthesized, actionable conclusions.
This is precisely what makes them powerful. And it is precisely what makes the risk profile fundamentally different.
The context problem
To get useful output from an LLM, you must provide useful input. You cannot ask an LLM to review your authentication architecture without describing it. You cannot ask it to triage a security incident without providing incident details — the affected systems, indicators of compromise, log excerpts, forensic artifacts.
The specificity that produces useful answers is the same specificity that constitutes sensitive exposure.
A developer pasting an authentication module into an LLM for security review is transmitting proprietary business logic, security-critical code, and implicit information about the broader system — all in a single interaction. An incident responder asking an LLM to analyze a suspicious process tree is sharing real-time operational intelligence about an active attack.
The aggregation problem
Individual interactions may seem manageable in isolation. But organizations that integrate LLMs into security workflows — ticketing systems, code review pipelines, SOC tools — create a cumulative data flow far more significant than any single query.
An LLM that analyzes security incident tickets over weeks and months builds a composite picture of your environment that no single ticket reveals: which systems are repeatedly targeted, which vulnerability classes recur, which teams respond slowly to which alert types, what your technology stack looks like, what your detection gaps appear to be.
This aggregated intelligence is extraordinarily valuable to an adversary — and it now exists, in concentrated form, on infrastructure you do not control.
The synthesis problem
Search engines surface information. LLMs produce conclusions. When a cloud LLM analyzes your incident data and architecture context together, it is performing the cognitive work of understanding your security posture — and doing so on someone else’s infrastructure.
If that analysis is ever accessible to an adversary, they do not receive raw data. They receive interpreted intelligence: prioritized attack paths, identified control gaps, understanding of your detection capabilities and their limits.
The prompt injection problem
There is a risk category with no search engine equivalent: prompt injection. An LLM that analyzes content from your environment — emails, tickets, log entries, documents — can be manipulated through that content.
A sophisticated attacker who knows your organization uses an LLM for security triage can craft malicious artifacts specifically designed to contain hidden instructions that alter the model’s behavior: downplaying the severity of an incident, misclassifying a threat, or producing incorrect remediation recommendations.
The attack surface now includes everything the model is asked to read.
Part IVDomain-specific risks
Secure product development
When developers use LLMs to build or review security-critical code, they transmit proprietary implementations that may contain unreleased features, novel cryptographic approaches, or unique business logic.
The risk is not only confidentiality — it is also false assurance. A developer who asks an LLM “is this implementation secure?” and receives a confident affirmative may ship code with subtle vulnerabilities the model missed, with an audit trail that suggests a review was performed. This is arguably more dangerous than no review at all.
Secure architecture design
Architecture discussions require the most contextually rich inputs of any security domain — network topology, trust boundaries, authentication flows, data classification schemas, infrastructure vendors, and known legacy constraints. Together, these constitute a near-complete attack map.
There is also a subtler systemic risk: design convergence. If many organizations use the same LLM to design security architectures and the model consistently nudges toward similar patterns, the threat landscape homogenizes. Attackers who understand the model’s architectural preferences gain a probabilistic advantage across many targets simultaneously.
Penetration testing and vulnerability assessment
LLM-assisted penetration testing requires feeding in real system details to get useful attack path analysis. If an adversary gains access to the context or output of these interactions, they receive a prioritized vulnerability map of your environment — prepared by your own security team.
Security monitoring
Detection engineering with LLM assistance involves sharing your existing detection rules, your gaps, and your threat priorities. An adversary who understands what you are detecting is equally interested in what you are not detecting. LLM interactions in this domain can inadvertently reveal your blind spots as clearly as your capabilities.
Incident response
This is where the risk is most acute, for several compounding reasons:
- Incident response involves real-time operational intelligence during an active attack. Sending that intelligence to a cloud LLM at the exact moment an adversary may be observing your response creates an asymmetric information risk.
- The data involved frequently includes personal information of affected individuals, creating hard regulatory obligations that cloud LLM usage may directly violate — particularly under GDPR and NIS2.
- Incident data often becomes legal evidence. External transmission without proper data processing agreements can compromise forensic integrity.
- Time pressure during incident response is precisely when automation bias is highest. Analysts are most likely to accept LLM conclusions without sufficient scrutiny when they are most stressed and time-constrained.
Part VGovernance recommendations
The goal is not to avoid LLMs in security work. They offer genuine capability acceleration that security teams cannot afford to ignore. The goal is to use them with a risk posture commensurate with the sensitivity of the domain.
- Establish a data classification policy for LLM interactions. Define explicitly which categories of data are permissible to send to which types of LLM deployment. Generic queries about CVE classes or compliance standards carry very different risk than queries involving real system context, actual incident artifacts, or proprietary architecture details.
- Adopt a tiered deployment model. Public cloud LLMs are appropriate for generic, non-context-specific tasks — learning about a vulnerability class, drafting policy templates, understanding a compliance framework. On-premise or private-deployment LLMs should be required for any interaction involving real organizational context: code review of proprietary systems, architecture analysis, incident triage, or detection engineering.
- Implement data sanitization pipelines. Where cloud LLM use is unavoidable, build systematic sanitization processes that remove or anonymize identifying information before data reaches the model. System names, IP addresses, vendor-specific configuration details, and personnel information can often be abstracted without losing analytical value.
- Apply prompt injection mitigations in any LLM-integrated security tooling. Any pipeline where an LLM analyzes externally sourced content — emails, tickets, log entries, threat feeds — must include defenses against adversarial content designed to manipulate the model’s behavior. Treat this as a first-class security requirement, not an afterthought.
- Scrutinize provider terms rigorously and continuously. Data retention policies, training data practices, subprocessor relationships, and data residency commitments vary significantly across providers and change over time. Security and legal teams should own ongoing review of these terms for any LLM integrated into security workflows.
- Maintain human judgment as the authoritative layer. LLM outputs in security contexts should be treated as structured suggestions requiring expert validation, not conclusions. Establish explicit review requirements for high-stakes LLM outputs — architectural recommendations, incident triage classifications, penetration test findings — and document those reviews.
- Monitor your LLM usage as you would any privileged access. Log what is sent to LLM systems. Detect anomalous query patterns. Treat LLM API integrations as high-privilege data pathways with corresponding access controls, monitoring, and regular review.
Conclusion
The security community has spent years thinking carefully about where sensitive data lives and who can access it. We have built data classification frameworks, access control models, and data loss prevention systems to protect what we know about our own vulnerabilities.
We have been less rigorous about what happens when that knowledge flows outward through the tools we use to do security work.
Search engines distributed this risk across many thin interactions. LLMs concentrate it. A single, well-integrated LLM that supports your developers, architects, penetration testers, SOC analysts, and incident responders may, over time, accumulate a more complete picture of your organization’s security posture than any single internal system holds — and it exists on infrastructure outside your control, subject to data practices outside your governance.
As AI-native security tools become mainstream — AI vulnerability scanners, AI SOC services, AI-assisted incident response — this question does not diminish. It grows.
The organizations that govern this well will capture the productivity benefits of LLM-assisted security work while managing the exposure it creates. The organizations that do not will have traded one kind of security risk for another — and may not know it until the cost becomes visible.