Blog SOC Engineering
What Should We Monitor? How SOCs Define and Prioritise Use Cases
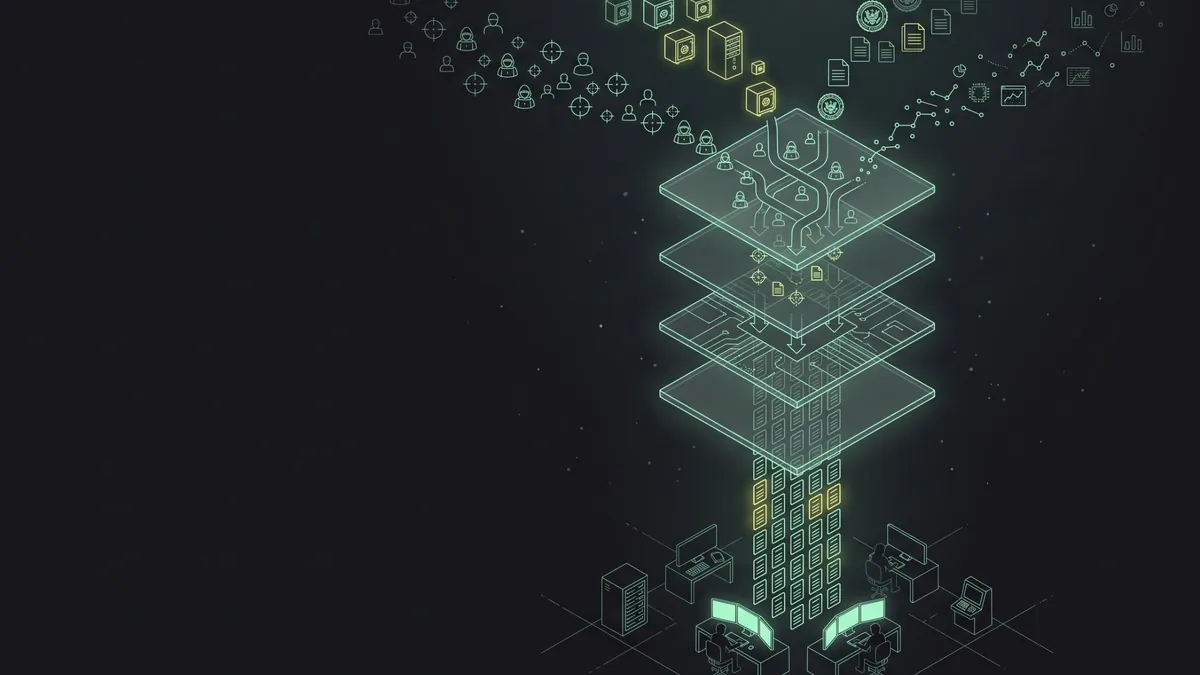
Every SOC could monitor an infinite number of things with a finite number of analysts. The four approaches teams use to decide what actually makes the rule set — what each gets right, where each fails, and the layered order in which to combine them.
Introduction
Security Operations Centres face a fundamental tension: the universe of things they could monitor is infinite, while analyst capacity, tool licensing and budgets are finite. Defining and prioritising monitoring use cases is therefore not a one-time configuration task. It is an ongoing strategic discipline that decides whether a SOC delivers real security value or merely generates operational noise.
The question “what should we monitor?” sounds simple. In practice it sits at the intersection of threat intelligence, business risk management, compliance obligations and operational capability. Answer it too broadly, and analysts drown in alerts without ever finding the signal. Answer it too narrowly, and real attacks go undetected.
It gets harder in multi-tenant environments. A managed provider serving several customers — or an internal SOC serving several business units — has to reconcile different industries, risk appetites, technology stacks and maturity levels with one rule set. A detection that is critical for a bank may be irrelevant for a manufacturer; a rule that fires hundreds of times a day in one environment may never fire in another.
Over the years I have seen four principal philosophies for answering the question. Each embodies a different belief about where detection value originates, and each has to be judged across five dimensions that together represent the full picture of a monitoring programme:
- Analyst — day-to-day usability, cognitive load, rule quality and the investigation experience.
- Organisational cost — tooling, licensing, headcount, scalability and time to value.
- SOC management — reporting, governance, service delivery and team management.
- Alert priority — how the approach shapes the urgency, triage and analysis of the alerts it produces.
- Use case severity — how accurately it calibrates “critical” against “low”.
Part IThreat-driven — start from the adversary
Threat-driven approaches start from the attacker and work backwards to detection logic. Instead of asking “what does our infrastructure produce?”, they ask “what do attackers actually do, and what evidence would they leave?” Executed well, this produces the most operationally relevant use cases of any approach — but it demands expertise and investment to maintain.
MITRE ATT&CK mapping gives you a structured, community-maintained taxonomy of adversary techniques. Mapping detection requirements to technique IDs enables coverage visualisation, gap analysis and access to a large library of community-written Sigma rules. Its greatest strength is shared vocabulary: analysts, management and customers can talk precisely about what is and isn’t detected.
Threat-intelligence-led detection filters that landscape through sector-specific intelligence — commercial feeds, ISACs or your own research — to the actors actually targeting your industry and the techniques they favour. The result is a highly relevant rule set with a clear justification: “we monitor for the specific actors targeting your sector.” Triage accelerates when analysts have attribution context; a known APT tool signature warrants faster escalation than a generic anomaly.
Threat modelling (STRIDE, PASTA) maps potential attack paths through your architecture and places detection logic where attackers would have to pass. The output is grounded in real attack paths rather than generic technique categories, and severity assignment is accurate because it derives directly from the business impact of each modelled path.
Red and purple team output is the highest-fidelity input available: rules built from real attack behaviour in the actual environment. Purple team exercises in particular, where the SOC works alongside the red team, directly close proven gaps. The resulting priorities are credible and defensible.
Where it shines: detection relevance, shared vocabulary, a strong narrative for stakeholders, kill-chain awareness that enables accurate severity. Where it hurts: it does not scale without skilled people; intelligence feeds are expensive and lag reality; threat modelling is per-environment and costly to maintain; red-team input is infrequent; and a pure focus on targeted actors leaves blind spots for generic, opportunistic threats.
Part IIRisk- and asset-driven — start from what you protect
Risk- and asset-driven approaches start from a different question: “what are we trying to protect, and what happens if we fail?” Monitoring investment becomes proportional to business value at risk, and severity ratings are grounded in business impact — the most credible form of calibration available.
Crown-jewel analysis identifies the data, systems and processes whose compromise would hurt the business most, and concentrates monitoring there. It creates a clear hierarchy: an alert touching a defined crown jewel is automatically elevated. It is intuitive, easy to explain to executives, and it produces naturally calibrated severity from asset criticality tiers.
Business impact analysis (BIA) quantifies the financial, operational and reputational impact of security events on key business processes. Priority decisions become straightforward: an alert on a system with a one-hour recovery objective warrants immediate escalation by definition. A BIA often already exists for disaster recovery purposes, so the SOC can reuse the work.
Attack surface mapping inventories every known entry point — internet-facing systems, identity providers, supply-chain connections and shadow IT — and raises default severity for anything publicly exposed. It is increasingly automatable through attack surface management tooling.
Where it shines: severity grounded in actual impact; no over-monitoring of low-value assets; priorities that executives and boards accept. Where it hurts: attackers pivot through low-value assets to reach crown jewels, so lateral-movement gaps appear; organisations frequently cannot agree on what their critical assets are; criticality shifts as the business changes; BIA language does not translate directly into detection logic; and impact alone ignores likelihood.
Part IIICompliance- and baseline-driven — start from the standard
Compliance and baseline approaches take monitoring requirements from externally specified standards: regulatory frameworks, industry benchmarks or minimum coverage guarantees. They are the lowest-effort route to a documented baseline and provide the clearest audit trail. Their weakness is structural: regulatory mandates are designed for auditors, not attackers, and the two have very different objectives.
Regulatory requirements (NIS2, PCI DSS, ISO 27001, DORA) mandate specific monitoring — access to privileged accounts, data transfer logging, authentication events — and so define a non-negotiable floor. Every rule has an auditable justification, and alert urgency can be tied to breach-notification timelines such as the 72-hour GDPR window. But compliance coverage was never designed to map to real attack paths, and the false confidence it creates is among the most dangerous failure modes in security programme design.
Community rule libraries (Sigma) provide thousands of maintained detections aligned to ATT&CK techniques, dramatically reducing time-to-detection for teams without capacity for custom development. The SIEM-agnostic format avoids lock-in. The community-assigned severity, however, is a starting point only and has to be recalibrated to each environment before deployment.
A log source coverage matrix ensures every source feeding the SIEM has at least a minimum set of associated rules, preventing “dark” sources where data is collected but never monitored. It is not sophisticated, but it is a simple governance mechanism that is valuable during onboarding and useful for communicating monitoring scope.
Where it shines: clear external justification for every rule; fastest path to a documented baseline; free, portable rule libraries; reusability across organisations in the same regulated sector. Where it hurts: compliance is not security; community severity ratings need recalibration; false-positive rates are high without tuning; and it cannot be the primary strategy — it treats audit scope as a threat model.
Part IVData- and analytics-driven — start from what actually fires
Data-driven approaches treat the SOC as a measurement system first and a detection system second. Rather than asking “what should fire?”, they continuously ask “what is firing, how good are those signals, and how do we improve?” They are operationally powerful but require real maturity to implement.
Detection-as-code and rule lifecycle management treats detection rules like software: version control, automated testing, CI/CD deployment and performance metrics. Alert quality is measured continuously — true-positive rate, mean time to triage, volume per rule — and under-performing rules are retired rather than left to generate noise. Severity assignments are validated in a test environment before they reach production, which significantly reduces the risk of a miscalibrated critical rule flooding analyst queues.
UEBA and behavioural baselining builds statistical baselines for users, hosts and service accounts and alerts on significant deviation. It catches unknown and novel patterns that static rules cannot — particularly insider threats and slow-burn credential abuse — and dynamic entity risk scores add a layer of context-aware prioritisation: a privileged account showing five anomalies scores higher than a standard user showing one, automatically. The cost is high: licensing, long baselining periods, and black-box explainability problems.
Alert-fatigue-driven prioritisation uses real alert volume and true/false-positive data to recalibrate which use cases deliver value and which merely consume analyst capacity. It is reactive — it optimises existing rules rather than identifying coverage gaps — but it is the most honest signal available about whether severity assignments are correct. A rule with a two-percent true-positive rate firing five hundred times a day is not a detection; it is a cost centre masquerading as one.
Where it shines: it is the only approach that validates detection quality with real data; UEBA detects what static rules miss; fatigue reviews directly improve analyst capacity and morale; detection-as-code scales quality governance across large portfolios. Where it hurts: the highest maturity requirement of all four; black-box alerts are hard to triage and explain; detection-as-code requires an engineering culture shift; fatigue analysis does not guide new use case creation; and volume-based suppression can hide rare, critical alerts.
Part VThe four approaches side by side
| Approach | Effort | Strongest contribution | Biggest risk |
|---|---|---|---|
| MITRE ATT&CK mapping | Medium | Shared vocabulary, coverage visibility, reusable community rules | Every technique looks equal; high coverage percentage mistaken for detection quality |
| Threat-intelligence-led | High | Relevance and attribution context that speeds triage | Expensive feeds; blind spots for untargeted threats; APT focus inflates severity |
| Threat modelling | High | Detections derived from real attack paths; accurate severity | Per-environment effort; needs senior skills; not reusable |
| Red / purple team output | High | Highest-fidelity rules, proven gaps closed | Infrequent; priorities can break when the environment changes |
| Crown-jewel analysis | Medium | Focus on what matters; severity from asset tiers | Lateral movement through low-value assets goes unseen |
| Attack surface mapping | Medium | Finds shadow IT; higher priority for exposed assets | Identifies assets, not attack logic; exposure is not severity |
| Regulatory requirements | Low | Auditable justification; reusable in a sector | Compliance is not security; false confidence at board level |
| Community libraries (Sigma) | Low | Near-zero cost baseline, deployed quickly | High false positives; severities calibrated for someone else’s environment |
| Detection-as-code | High | Quality gates; data-driven retirement of poor rules | 12–18 month build; demands software engineering practice |
| UEBA / baselining | High | Detects novel attacks; context-aware risk scores | Black-box explainability; highest licensing cost |
| Alert-fatigue prioritisation | Medium | Honest signal about which rules deliver value | Reactive only; rare critical alerts must not be downgraded for infrequency |
Part VIThe approach that works — a layered strategy
No single approach is sufficient on its own. Each of the four compensates for weaknesses in the others: threat-driven approaches provide relevance, risk-driven approaches provide business alignment, compliance-driven approaches provide auditability, and data-driven approaches provide continuous quality validation. The most effective SOCs combine all four — in a deliberate sequence that matches implementation maturity to return on investment.
ATT&CK without threat intelligence produces broad but unfocused coverage. Threat intelligence without ATT&CK lacks the structure to turn it into consistent, comparable detection logic. Apply them together from day one.
- Threat-informed foundation: ATT&CK + sector threat intelligence + log source coverage matrix. Start with structure and relevance at the same time. ATT&CK provides the vocabulary, community rule library and kill-chain framework; sector-specific intelligence filters the technique landscape to what is actually relevant to your threat profile; the coverage matrix ensures no ingested source goes unmonitored. Together they establish a baseline that is comprehensive and operationally justified, at relatively low cost and with fast deployment.
- Business context: onboarding workshop + crown-jewel analysis. Generic rules become dangerous without knowing what matters to the specific organisation. These two steps cost almost nothing in tooling and dramatically improve severity calibration and alert priority from day one. They are the most consistently under-invested step in managed programmes — and the one with the highest marginal return.
- Governance: SLA tiering + continuous review cycles. SLA tiers make alert priority operationally concrete and contractually enforceable. Continuous reviews — ideally quarterly — prevent rule decay, maintain severity accuracy and demonstrate ongoing value. This layer separates SOCs that improve over time from those that stagnate.
- Advanced: UEBA or detection-as-code, when the foundation is solid. These approaches have the highest ceiling but are only viable on top of a stable base. Deploy them selectively where data volume, budget and environment stability justify the investment. Detection-as-code is the governance layer that scales quality across a large portfolio in the long run.
Two critically undervalued approaches
The onboarding workshop is consistently underrated. At near-zero cost, it captures context that no automated tool can produce: legacy systems, past incidents, undocumented business risk, the application nobody is allowed to touch. Every severity and priority decision downstream is more accurate because of it. Most SOCs treat it as an administrative checkbox; it should be treated as the most important analytical input in the programme.
Alert-fatigue-driven prioritisation is often avoided because it feels reactive. But it is the most honest signal about whether the monitoring programme works. A rule firing five hundred times a day with a two-percent true-positive rate is operational debt, not a detection. Regular fatigue analysis keeps the whole detection system credible and directly frees the analyst capacity needed to invest in higher-value use cases.
The one approach to avoid as primary strategy
Relying on regulatory compliance as the primary driver for use case definition is the most common failure mode in managed security services. It creates the illusion of coverage, gives stakeholders false confidence, and produces rules designed for auditors rather than attackers. Compliance requirements should run as a parallel constraint that guarantees a minimum baseline — never as the engine that drives use case design.
Conclusion
Defining and prioritising security monitoring use cases is one of the most consequential decisions a SOC makes — and one of the least systematically governed. The four approaches above each represent a legitimate philosophy for allocating finite detection capacity, and each has real merits when judged from the perspectives of analysts, organisations, managers, alert priority and severity calibration.
The practical reality is that they are not competing alternatives but complementary layers. ATT&CK and community libraries provide the baseline. Workshops and crown-jewel analysis provide business alignment. Sector intelligence provides relevance. Continuous review and fatigue analysis provide operational discipline. And for mature programmes, detection-as-code and UEBA provide the scalability and novel-threat coverage that static rule sets cannot.
The organisations that build the most effective monitoring programmes are not the ones with the largest rule libraries or the most sophisticated tooling. They are the ones that make deliberate, documented and continuously reviewed decisions about what they monitor and why — and that keep the discipline to retire what no longer works and invest in what does.